I just kicked off Fable doing a bakeoff, training LoRA weights with a few image diffusion…
I just kicked off Fable doing a bakeoff, training LoRA weights with a few image diffusion (DiT) models.
This is an area I know very little about.
I fed it images, briefs, and judging criteria for guidance, and now it is renting GPUs on @runpod, downloading models, and configuring+executing training runs, reviewing results, and adjusting.
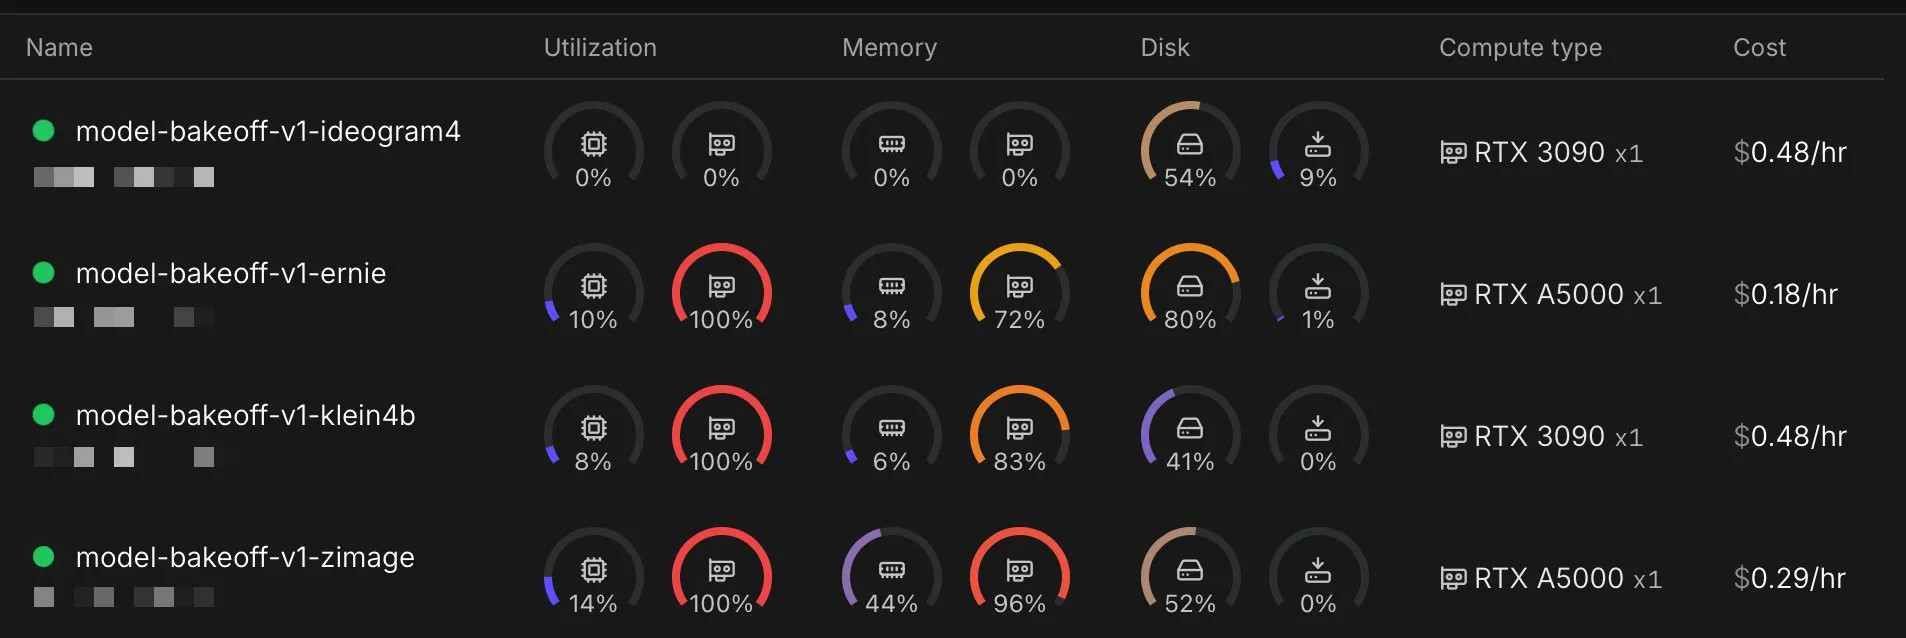
It’s so crazy it can even attempt this … it’s a little nerve-racking waiting to see how it turns out. 🙃
result:
I am dazzled… Trained up LoRA weights with open source model, remotely, renting Nvidia chips, and generated an automated re-ranker based on human reviews, and can now generate on-style tiny icons both on remote CUDA, and local Mac w/MLX.
Thousands of them🤯
TIL: If you can keep a lot of the experiment organized in context and recorded thoughtfully in logs on disk, a good [llm] model can do an amazing job of summarizing it and explaining it from multiple perspectives. One area I discovered was weak, though, was follow-on and productionizing for repeatability. In service of meeting a /goal, model tended to ‘work around’ things and sometimes not clean up well.